
Quick answer: A 99.999% uptime data center target (“five nines”) allows about 5.26 minutes of downtime per year, roughly 26 seconds per month. In a data center, that level is only reachable when redundancy lets components fail and be replaced without service impact, and when procedures keep people from causing outages, since one hands-on repair outlasts the whole annual budget.
Five nines shows up in RFPs, SLAs and sales decks more often than it shows up in measured results. That gap is worth understanding before you commit to a 99.999% uptime data center target or accept one from a provider.
This article is for CTOs, infrastructure leaders and operations managers who set availability targets or evaluate the partners behind them. It covers the downtime math, how redundancy gets you there, why human factors decide the outcome, and where field execution affects availability.
One ground rule up front: we treat five nines as an industry benchmark. It is a property of an entire service architecture, and no single field provider can promise it on its own. That includes us.
What does 99.999% uptime mean for a data center?
It means the service is down no more than 0.001% of the measurement period, which works out to about 5 minutes and 16 seconds in a 365-day year.
Availability is the percentage of a defined measurement period during which a service operates within its agreed performance, so 99.999% availability means no more than 0.001% of that period may be lost to outages.
Two formulas cover most discussions:
- Time-based: availability = uptime / (uptime + downtime).
- Reliability-based: availability = MTBF / (MTBF + MTTR), where MTBF is mean time between failures and MTTR is mean time to repair.
The second formula is the more useful one for planning. It shows that you can improve availability by failing less often or by recovering faster, and that at five nines, recovery has to be almost instant from the service’s point of view.
Downtime per year at each level of nines
Here is the allowed downtime for common targets, calculated on a 365-day year (525,600 minutes) and a 30-day month.
Availability | Common name | Downtime per year | Downtime per month | Downtime per week |
|---|---|---|---|---|
99% | Two nines | 3.65 days (87.6 h) | 7.2 h | 1.68 h |
99.9% | Three nines | 8.76 h | 43.2 min | 10.1 min |
99.95% | Three and a half nines | 4.38 h | 21.6 min | 5.04 min |
99.99% | Four nines | 52.56 min | 4.32 min | 1.01 min |
99.999% | Five nines | 5.26 min | 25.9 s | 6.05 s |
99.9999% | Six nines | 31.5 s | 2.59 s | 0.6 s |
Each extra nine cuts the budget by a factor of ten. The jump from four to five nines takes you from under an hour a year to about five minutes.
What 5.26 minutes a year looks like in practice
Put the number next to ordinary events and it gets clearer:
- A controller or firmware reboot that takes six minutes uses more than a full year of budget.
- A one-hour hands-on repair is about 11 times the annual allowance.
- A four-hour repair window would consume roughly 45 years of five nines budget.
The conclusion is not that repairs must be faster than five minutes. It is that at five nines, repairs cannot count as downtime at all. The architecture has to absorb the failure while someone replaces the part.
How does redundancy get a data center to five nines?
Redundancy works because the availabilities of parallel paths combine in your favor, while components in series combine against you. The math is simple. The assumptions behind it are where designs fail.
In series, availabilities multiply. Three components at 99.99% each, all required for the service, give about 99.97%. Every single point of failure pulls the total down.
In parallel, you multiply the unavailabilities instead. Two independent paths at 99.9% each give 1 − (0.001 × 0.001) = 99.9999%. That is how modest components add up to very high service availability.
The word doing the work there is “independent.” Common-mode failures break the math:
- A and B power feeds that trace back to the same upstream panel.
- Two “diverse” fiber routes that share one conduit for 200 meters.
- The same firmware bug on both members of a redundant pair.
- One flawed method of procedure applied to both sides of a system.
On the facility side, Uptime Institute’s Tier Standard frames resilience in terms of topology, such as concurrent maintainability at Tier III and fault tolerance at Tier IV, rather than availability percentages. Be wary of material that equates a tier with a specific number of nines. Our article on Uptime Institute tiers and on-site staffing covers how the operational side of those tiers is framed.
Why human factors decide five nines
Most designs can reach five nines on paper. People and procedures decide whether they do in production.
Uptime Institute’s Annual Outage Analysis 2025 found that nearly 40% of organizations had suffered a major outage caused by human error over the previous three years, and that 85% of those incidents came from staff failing to follow procedures or from flaws in the procedures themselves. The 2026 edition reports that failure to follow established procedures remains the leading driver of human error-related outages, and that power remains the leading cause of impactful outages, with UPS systems, transfer switches and generators dominant.
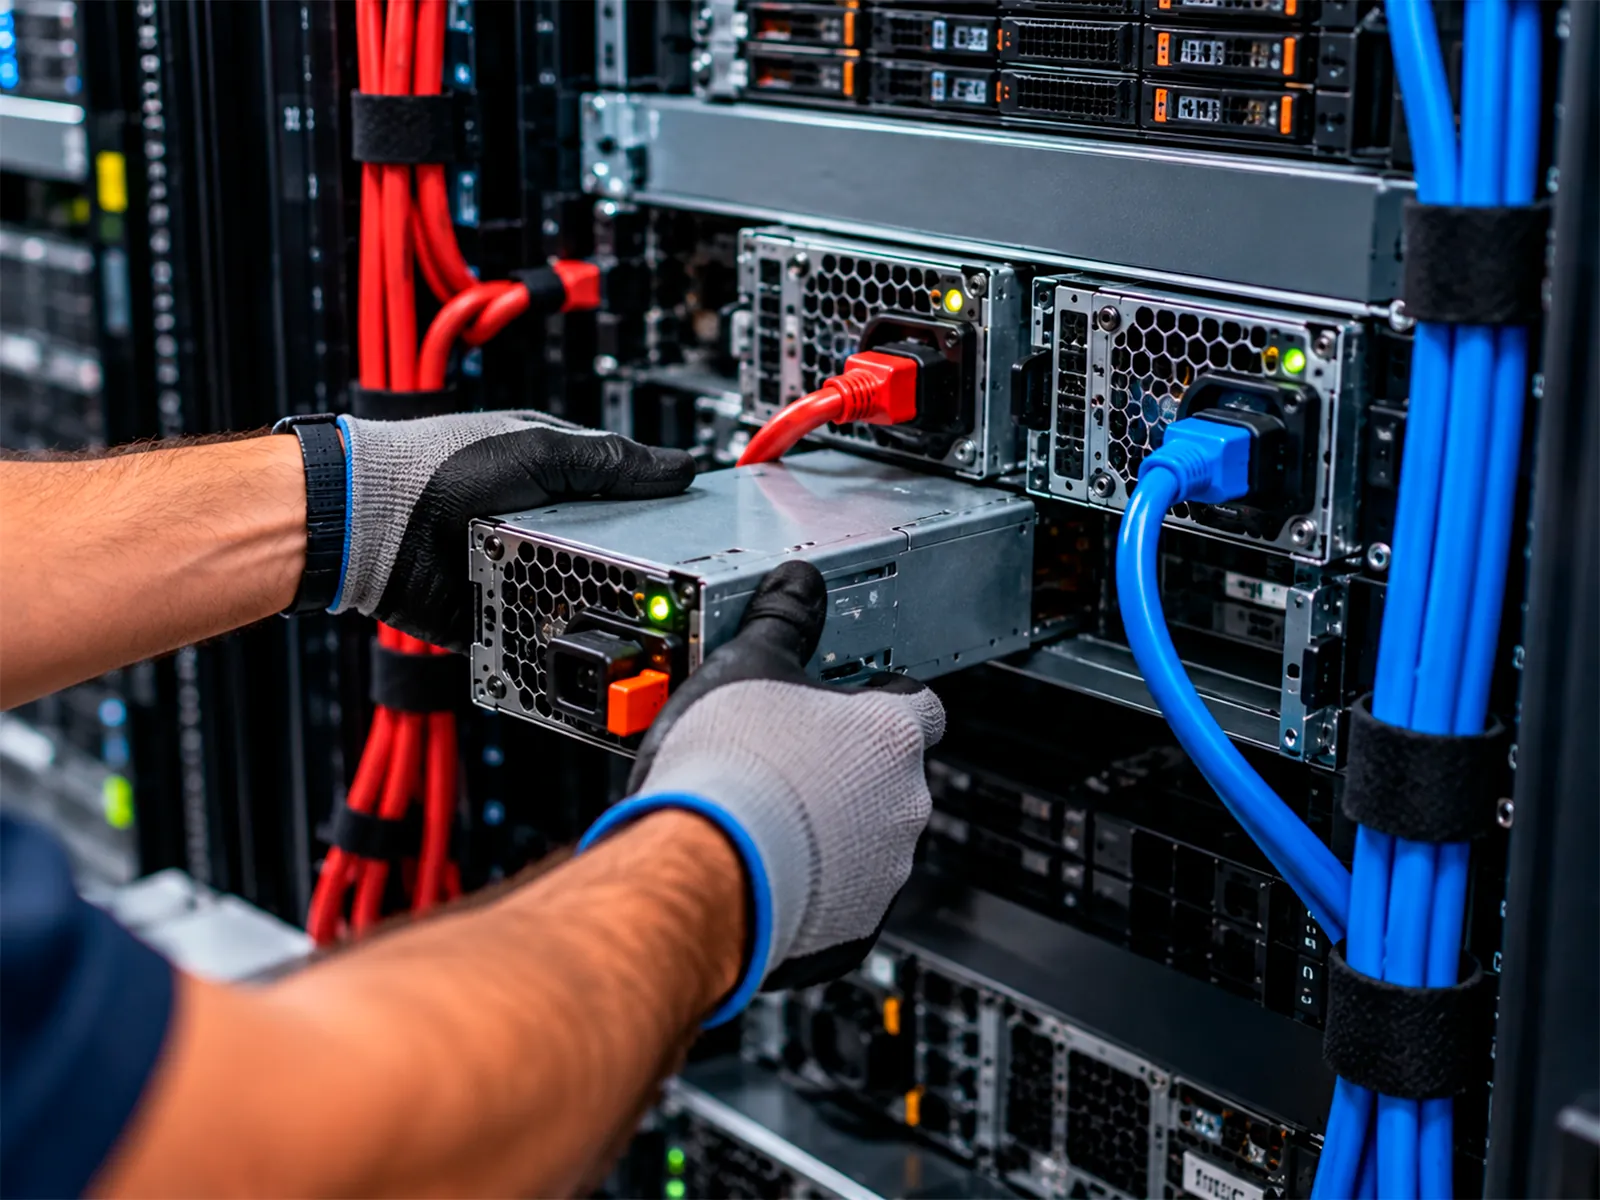
In the field, those findings look very specific. A technician pulls the live power cord instead of the failed one because A and B cords are the same color and unlabeled. A redundant line card is reseated during a window that was approved for the other chassis. A jumper is moved during a cleanup and takes the “backup” path down weeks before anyone needs it. None of these are exotic. All of them are preventable with labeling, written procedures and a second person checking before anything is pulled.
The degraded window: where field execution affects availability
When a redundant component fails, the service keeps running, but at N instead of N+1 until the part is replaced. The risk of a second failure during that window grows with its length, so time to restore redundancy matters even when no downtime is recorded.
An illustrative example, with round numbers chosen for clarity: suppose the surviving unit in a redundant pair has a 1-in-1,000 chance of failing on any given day. A same-day replacement leaves you exposed for a fraction of a day. Waiting three days for a part to clear a loading dock carries roughly three times the exposure of a one-day wait. The redundancy was designed correctly in both cases. Only the field response differed.
What stretches the degraded window, in our experience:
- Badge and escort requests that take days to approve.
- Spares that are not on site, or are on site but not where the inventory says.
- RMA shipments sitting in receiving without anyone tracking them.
- Unclear access procedures at colocation sites.
- Technicians unfamiliar with the platform who need a second visit.
This is also why we track time to restore redundancy separately from response time. They are different numbers, and the second one is closer to what protects availability. For how response and restore times are defined in contracts, see our guide to data center SLA response time benchmarks.
Five nines readiness checklist for a 99.999% uptime data center
Use this list before you publish a 99.999% target or accept one in a contract.
- Downtime is defined: what counts as down, how partial degradation is treated, and whether planned maintenance is excluded.
- The measurement point is agreed (service endpoint, not individual devices).
- Redundancy has been proven by failover tests, not by drawings alone.
- Common-mode risks are reviewed: shared upstream power, shared conduits, shared firmware.
- Every maintenance task on a redundant system has a written procedure with a peer check.
- A/B feeds and paths are labeled on site exactly as they appear in the drawings.
- Spares are stocked for every component whose failure drops a system to N.
- Field response and time to restore redundancy are tracked as separate metrics.
- Post-incident reviews feed changes back into procedures and training.
If several boxes stay unchecked, a four nines target with honest measurement is usually worth more than a five nines target nobody can verify. Our guide to calculating the ROI of uptime improvements shows how to decide whether the next nine pays for itself.
How Hype Telecom helps
Hype Telecom does not sell availability percentages. We work on the physical side of the degraded window. Through Smart Hands and First Line Maintenance (FLM) services, we provide 24/7/365 field support with a historical sub-4-hour emergency response across 50+ active sites in the U.S. and Brazil — an arrival commitment, with SLAs configured per contract — and a 95% first-visit resolution rate. Our field teams are OSHA 10h/30h trained, our technicians hold CompTIA Server+, Network+ and A+ credentials, and we execute to the customer’s written procedures, including peer checks before work on redundant systems. Our coordination team manages access, spares tracking and closure evidence so a failed component is replaced before a second failure has time to matter.
To compare field partners on the metrics that protect availability, download the FLM Provider Evaluation Guide.
Frequently asked questions
On a 365-day year, 99.999% availability allows about 5.26 minutes of downtime, or roughly 5 minutes and 16 seconds. That is about 26 seconds per 30-day month and around 6 seconds per week. For comparison, 99.99% allows about 52.6 minutes per year and 99.9% allows about 8.76 hours per year.
The difference is a factor of ten in allowed downtime: about 52.6 minutes per year at four nines versus about 5.26 minutes at five nines. In practice, four nines can tolerate a short unplanned outage each year. Five nines effectively requires that no repair, reboot or maintenance task is ever visible to the service.
A single facility can support very high availability, but five nines is normally reached at the service level, through redundant paths, redundant sites or both. Shared dependencies such as utility feeds, fiber routes and upstream networks make it hard for one building to carry the whole target. Measure it at the service endpoint, not at individual devices.
No. The Tier Standard describes topology objectives, with Tier III built around concurrent maintainability and Tier IV around fault tolerance. It is not defined by an availability percentage. A Tier IV design helps, but operations, procedures and staffing still decide the availability you actually measure. Treat any tier-to-nines conversion you see in marketing material with caution.
It depends on the contract. Many SLAs exclude scheduled maintenance windows, which can make a five nines figure look better than the user experience. If maintenance is excluded, check how windows are approved and capped. If it counts, the architecture must allow maintenance without service impact, which is what concurrent maintainability is designed to deliver.


2 Responses